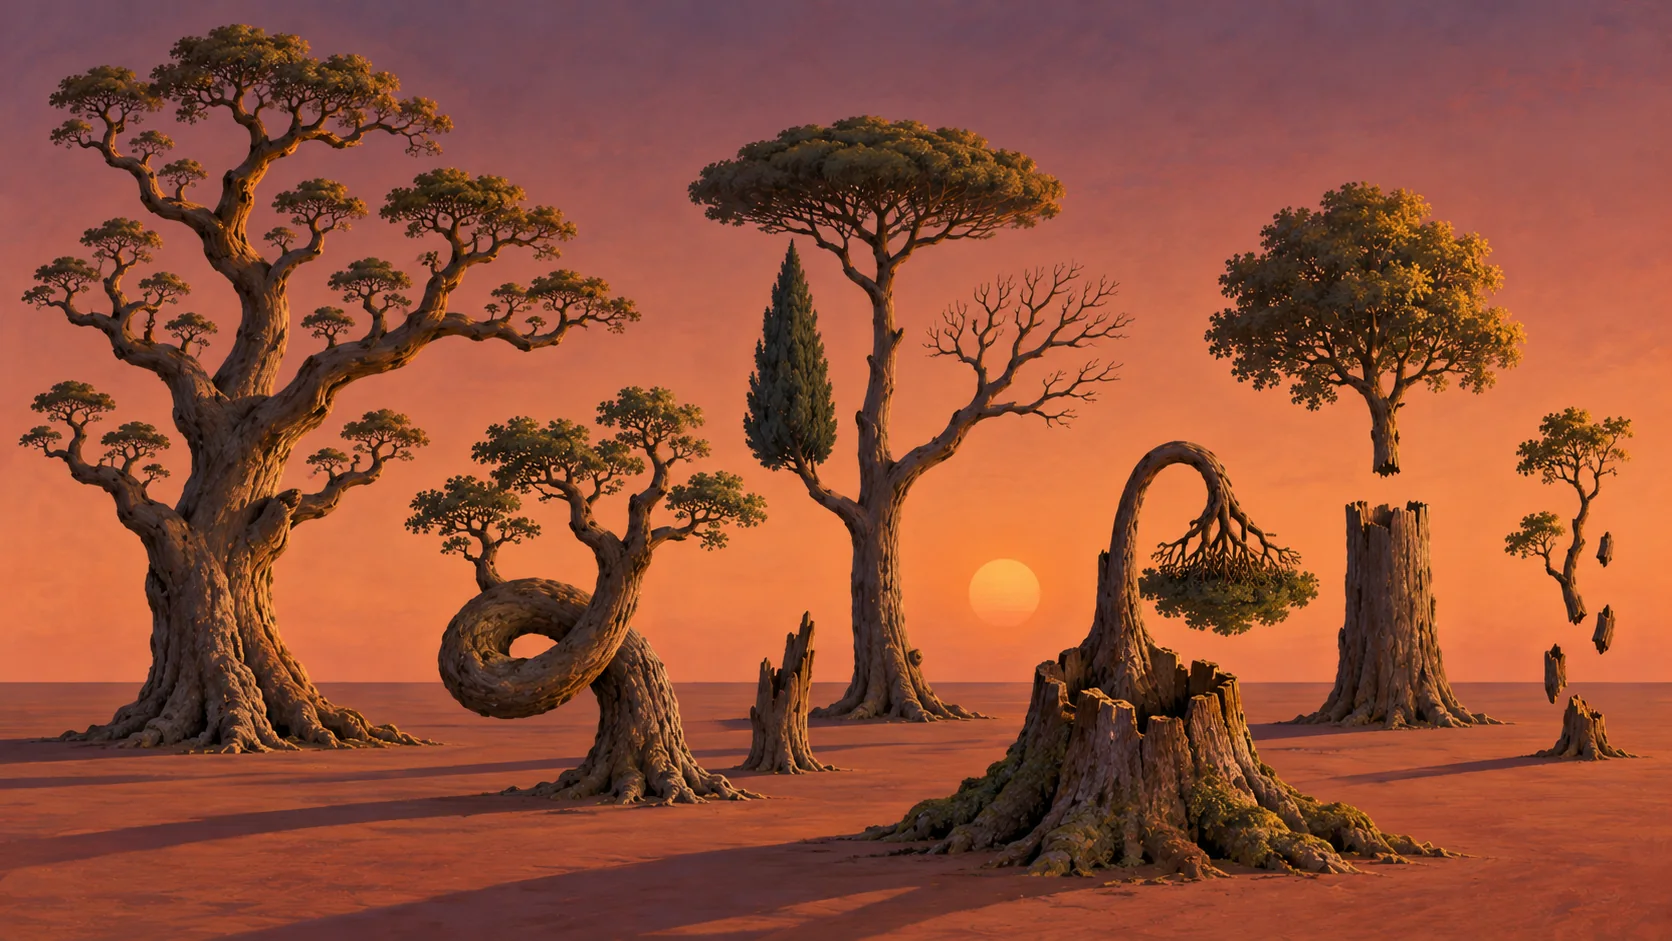
Neurons evolve in many ways: branching generalization and unrelated coexistence (superposition) exist side by side.
神经元的演化机制是多样的,分支泛化与无关特征的共存重叠共同存在。
Tap the dots to explore the scene点击光点,看看每棵树代表什么
Recursive Generalization and Superposition Are Both Right递归泛化与重叠都是对的
We tracked 240 neurons of Pythia-160M across 40 training checkpoints to see how their features appear and change.我们在 40 个训练检查点上追踪了 Pythia-160M 的 240 个神经元,观察它们的特征如何出现和变化。
Superposition and generalization happen together重叠与泛化同时发生
By tracking neurons in Pythia-160M throughout training, we found that superposition and recursive generalization are not mutually exclusive. Instead, they happen together most of the time.
We also observed two previously unreported learning patterns: replacement, where a neuron drops what it has learned and switches to something new, and sporadic features, where weak features appear only briefly.
Nick Cammarata’s recent essay, Neural Networks Are Already Clean, sparked a debate about why neurons respond to seemingly unrelated things. He argues that much of the evidence usually attributed to superposition was misread, partly because of weak tools and older model designs. Instead, he proposes recursive generalization as the main explanation.
Nick Cammarata 最近的文章《Neural Networks Are Already Clean》引发了一场讨论:神经元为什么会响应看似无关的东西?他认为,通常被归因于重叠的许多证据其实被误读了,部分原因在于工具较弱、模型设计较旧。他转而提出,递归泛化才是主要解释。
This post builds on that discussion with further experiments and thoughts on language models. Our investigation centers on these two ideas:
本文在这一讨论的基础上,补充了在语言模型上的进一步实验与思考。我们的研究围绕以下两个概念展开:
Recursive generalization递归泛化
A neuron starts by responding to a simple pattern, then gradually extends to related things, sometimes branching in several directions. Each step follows a connection, but the endpoints may look unrelated if we cannot see how the neuron got there.
In Toy Models of Superposition, networks represent more features than they have dimensions by placing features along overlapping, non-orthogonal directions. This definition does not require the features to be unrelated. Nick uses the term more narrowly: unrelated features share neurons because they can coexist with little interference, rather than because they share a meaningful connection.
在 Toy Models of Superposition 中,网络把特征放在相互重叠、非正交的方向上,从而表示比维度更多的特征。这一定义并不要求特征彼此无关。Nick 对这个词的用法更窄:无关的特征共享神经元,是因为它们可以几乎互不干扰地共存,而不是因为它们之间有什么有意义的联系。
We follow Nick’s usage here as we want to investigate the distinction he proposes—whether a neuron’s different responses develop through connected steps or bring together unrelated features.
Nick directly follows neurons through training in vision models, but his language-model analysis mainly works backward from already-trained models. Direct evidence of how these patterns develop during language-model training is still limited. Do we see recursive generalization, superposition, or both when we follow neurons as they learn? We explored this with Pythia-160M, whose public training data and intermediate checkpoints let us track how individual neurons change throughout training.
Nick 在视觉模型中直接跟踪了神经元在训练中的变化,但他对语言模型的分析主要是从已经训练好的模型往回推。关于这些模式在语言模型训练中如何发展,直接证据仍然有限。当我们跟随神经元的学习过程时,看到的是递归泛化、重叠,还是两者都有?我们用 Pythia-160M 探究了这个问题:它公开的训练数据和中间检查点,让我们能追踪单个神经元在整个训练过程中的变化。
Method方法
Our overall process looks like this: at each checkpoint, we collected the text passages that most strongly activated each neuron. An AI agent then described what the neuron responded to. A second agent read these descriptions in training order to identify how features appeared and evolved.
整体流程是:在每个检查点,我们收集最能激活每个神经元的文本片段;由一个 AI agent 描述该神经元在响应什么;再由第二个 agent 按训练顺序阅读这些描述,识别特征如何出现和演化。
Superposition and generalization happen together重叠与泛化同时发生
Our results suggest that superposition and recursive generalization are not mutually exclusive. Of the 240 neurons we tracked, only 14 showed recursive generalization alone, and only 11 showed superposition alone. Another 180 showed a mixture of learning patterns.
Learning patterns across the 240 neurons240 个神经元的学习模式
Classified by the AI agent. Click a row to list its neurons.由 AI agent 分类。点击一行可列出其中的神经元。
The figure below shows one example of a mixed neuron. By the end of training, it responds to both medical and programming terms. We traced these responses back to two seemingly unrelated early patterns: the verb “send” and capital letters. Each pattern then developed through a series of related steps.
Hover over a line to see how it formed, click a line to show only its family, and click a column to read the texts at that stage.把鼠标停在线上可以看它是怎么形成的,点击一条线只显示它所在的家族,点击一列可以阅读该阶段的原文。
Loading the neuron…正在加载神经元…
Feature evolution in a mixed neuron (L10/N2063).一个混合型神经元的特征演化(L10/N2063)。From left to right, the diagram follows its features across training checkpoints, with colors grouping related features into families.图从左到右沿训练检查点追踪它的特征,颜色把相关的特征归为同一个家族。
Still, our observations support Nick’s view that most features present at the end of training develop through generalization. This was the case for 213 of the 240 neurons. Superposition appeared more often early in training and became less common at later stages.
不过,我们的观察支持 Nick 的观点:训练结束时存在的大多数特征是通过泛化发展而来的,240 个神经元中有 213 个是这样。重叠在训练早期更常见,到后期变得较少。
The mechanism behind most of each neuron’s strongest responses after step 16,000.第 16,000 步之后,每个神经元大部分最强响应背后的机制。
Share of each mechanism over training各机制占比随训练的变化
Average over the 240 neurons of how much of the 10 strongest responses comes from features of each mechanism.在 240 个神经元上平均,最强 10 段响应中来自各机制特征的占比。
There are other patterns还有其他模式
Beyond the two most commonly discussed patterns—generalization and superposition—we also observed two other ways neurons evolved:
除了最常被讨论的两种模式,即泛化和重叠,我们还观察到神经元演化的另外两种方式:
Replacement替换
A neuron abruptly stops responding strongly to a previously learned feature and begins responding to a new, unrelated one.
神经元突然不再强烈响应之前学会的特征,转而响应一个新的、无关的特征。
Sporadic features零散特征
Weak, unrelated features appear briefly but never become a lasting part of what the neuron responds to.
微弱、无关的特征短暂出现,但从未成为神经元持久响应的一部分。
L0/N824, colored by mechanism.L0/N824,按机制上色。
Loading the neuron…正在加载神经元…
Overview总览
The example shows both patterns. Colors indicate how each feature developed: branch, unrelated coexistence, replacement, sporadic. Let’s focus on yellow and pink.
Around training step 6,000, a new feature involving approximate quantities, such as “about 10,” replaced the neuron’s earlier response to “MOT” strings.
This replacement feature, shown in yellow, soon generalized to expressions involving “around” (the red arrow).
这个以黄色表示的替换特征很快泛化到含“around”的表达(红色箭头)。
The final response at step 143,000第 143,000 步的最终响应
That branch eventually developed into the neuron’s dominant final response: “about” introducing the phrase that follows. The “MOT” feature did not reappear in the later checkpoints we examined.
Pink marks sporadic features, such as the “Caf” and “Café/Cafe” word forms, observed only at step 512. These appeared unrelated to the neuron’s other features and tended to involve surface patterns, such as spelling fragments. They looked like early features that never developed further. In our sample, they rarely persisted for more than one checkpoint.
In this sense, superposition and recursive generalization are both ways a neuron can become polysemantic, and neither provides a complete explanation on its own. Together with replacement and sporadic features, they often appear within the same neuron’s training history and may interact in complex ways. There may also be patterns we have not yet identified.
So a broader question is: what general principles govern how neurons learn?
因此,一个更大的问题是:神经元的学习遵循什么普遍规律?
A denoising mechanism?一种去噪机制?
Here is a tentative idea we call “denoising.” Early in training, a neuron responds without a clear pattern. As training progresses, these scattered responses gradually give way to strong responses to a few specific features.
Drag the slider or press play. Each bar is a feature; its height is how strongly the neuron responds to it.拖动滑块或点击播放。每根柱子是一个特征,高度是神经元对它的响应强度。
A schematic of denoising: two neurons trained on the same data gradually settle on different feature patterns. Neuron A becomes a “tree” of connected features; neuron B becomes separate “sticks.”去噪示意图:在相同数据上训练的两个神经元,逐渐稳定到不同的特征模式。神经元 A 变成一棵由相连特征组成的“树”,神经元 B 变成几根分开的“木棍”。
Why call it denoising? At initialization, a neuron has not yet learned clear preferences. In several examples in the interactive panel, its early responses appear weak and scattered. Most of the complex changes occur during early and middle training. Later, a clearer and more stable pattern emerges. This resembles a gradual clearing of noise. This picture is also consistent with previous work showing that, under certain conditions, neuron weights move from random initialization toward a few directions determined by the data.
One appealing part of this idea is that it can accommodate both recursive generalization and superposition. Think of images emerging from noise in an image generator. Initially, they all look similarly noisy. One eventually becomes a tree: its branches are connected, like features developing through recursive generalization. Another becomes a collection of separate sticks, like unrelated features coexisting through superposition. Even with the same training data, different neurons may settle on different patterns. In practice, a neuron may end up with several “trees” and several “sticks” together. The image at the top of this page shows such a mix.
The limitation is that it can’t explain replacement. An abrupt switch from one feature to another is hard to understand as a gradual clearing of noise. We therefore distinguish this denoising picture from evolution involving replacement, where a neuron’s direction changes along the way. We do not yet have a clear sense of what drives those changes.
We found that of the 240 neurons, 68 fit the denoising picture, 118 underwent feature replacement, and 54 showed no clear pattern. Here is one example from each group. Click a group to switch the panel below.
Colored by family. Each color marks a group of related concepts.按家族上色。每种颜色代表一组相关的概念。
Loading the neuron…正在加载神经元…
The denoising picture fits only about a quarter of the neurons. About half undergo replacement, which we can observe but do not yet understand. For roughly a fifth, we cannot even identify a clear learning pattern. To us, this suggests that the debate over how neurons learn—and why they become polysemantic—is far from settled.
These are some early results from a paper we are working on. They leave us with several open questions:
这些是我们正在撰写的论文中的一些早期结果。它们留给我们几个开放问题:
Why do these patterns occur?这些模式为什么会出现?
Do generalization, replacement, and the coexistence of unrelated features share a common cause, or do they arise from different mechanisms?
泛化、替换和无关特征的共存,是有共同的成因,还是源于不同的机制?
Have these neurons finished learning?这些神经元学完了吗?
Our intuition is that messy or changing features may suggest that individual neurons need more training, even when the model as a whole appears well trained. Would further training help them settle into stable functions?
They might lose out through local competition during generalization, then be taken over by other neurons or disappear altogether. This could happen even before the network reaches its capacity limit. But tracing what happens to them remains difficult.
How does the appearance and disappearance of features affect the model?特征的出现和消失如何影响模型?
Does it change the model’s internal representations or how easily we can steer its behavior?
它是否会改变模型的内部表征,或改变我们操控模型行为的难易程度?
Limitations局限性
We only studied Pythia-160M, a small, older language model. Next, we plan to study larger open models with public training checkpoints, such as K2 Horizon and OLMo.
We used GPT-6 Luna for the analysis, and its interpretations may be unreliable. When we repeated some of the analysis with Claude Opus 5.5, the two agreed in only about 40% of cases. This disagreement may reflect limitations of the agents, the difficulty of interpreting the activations, or both.
我们用 GPT-6 Luna 做分析,它的解读可能并不可靠。用 Claude Opus 5.5 重复部分分析时,两者只在约 40% 的情况下一致。这种分歧可能反映了 agent 的局限、激活本身难以解读,或两者兼有。
Notes注释
This terminology is contested. Our aim is to distinguish possible learning patterns, rather than settle the broader definition of superposition. Following Nick’s usage lets us examine his proposed distinction directly.这一术语存在争议。我们的目的是区分可能的学习模式,而不是为重叠的更广义定义下结论。沿用 Nick 的用法,让我们能直接检验他提出的区分。
Here, “related” means connected in form (e.g., iv → div), meaning (e.g., in → within → outside), function or usage (e.g., meeting agendas → parliamentary voting and speeches), or category (e.g., London → Amsterdam, both city names). A new feature can be related to any earlier feature, not just the one that appeared immediately before it.这里的“相关”指在形式(如 iv → div)、含义(如 in → within → outside)、功能或用法(如会议议程 → 议会投票与发言)或类别(如 London → Amsterdam,都是城市名)上存在联系。新特征可以与任何更早的特征相关,而不只是紧挨在它之前出现的那个。
@misc{gao2026neuronevolution,
title = {Recursive Generalization and Superposition Are Both Right},
author = {Gao, Lang and Zhang, Jinghui and Chen, Xiuying},
year = {2026},
url = {https://heartyhaven.github.io/blog/neuron-evolution/}
}